Slides 48–56
Use case 3: Energy pipeline compressor reliability
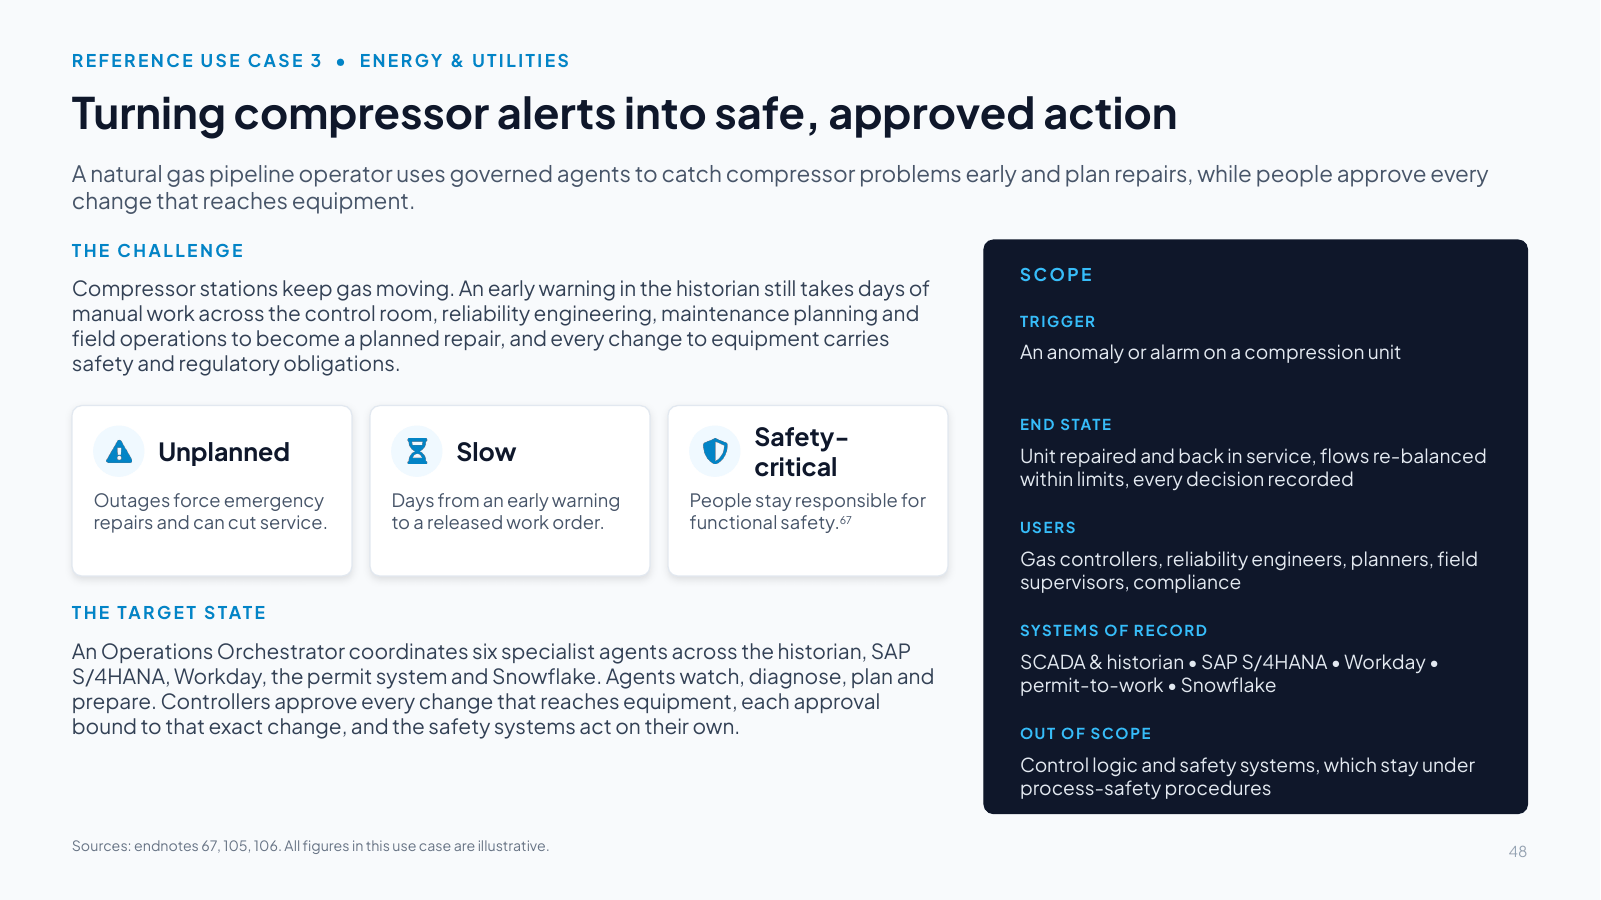
Turning compressor alerts into safe, approved action
Speaker notes
Talk track (two minutes): The third reference use case takes the control plane into operational technology, where an agent's action can reach physical equipment. It is written for a natural gas transmission operator and carries over to power utilities and to upstream and downstream oil and gas. As before, the architecture is vendor-neutral except for the transactional systems (SAP S/4HANA, Workday and Snowflake). Control systems, historians and safety systems are described generically.
The problem: most operators already stream vibration, temperature and pressure data to a historian, but turning an early warning into a planned repair still takes days of manual work, and unplanned outages force emergency repairs and can cut service. The work also sits under specific rules. Gas controllers need defined authority, adequate information, fatigue limits and managed alarm loads under the control room management rule [105]. Critical pipeline operators must segment OT from IT networks, control access and monitor continuously under TSA's security directive [106]. Current guidance also holds that people remain responsible for functional safety and that AI should not actively control OT without a human in the loop [67].
The target state: an Operations Orchestrator coordinates Condition Monitoring, Diagnostics, Flow & Load Advisor, Maintenance Planning, Crew & Permit and Compliance Records agents. The agents propose, and controllers approve every change that reaches equipment, with each approval bound to that exact change and valid for minutes. The independent safety systems act on their own.
All figures in this use case are illustrative. Replace them with the operator's own baseline during discovery. The companion handbook (Section 13) has the full detail.
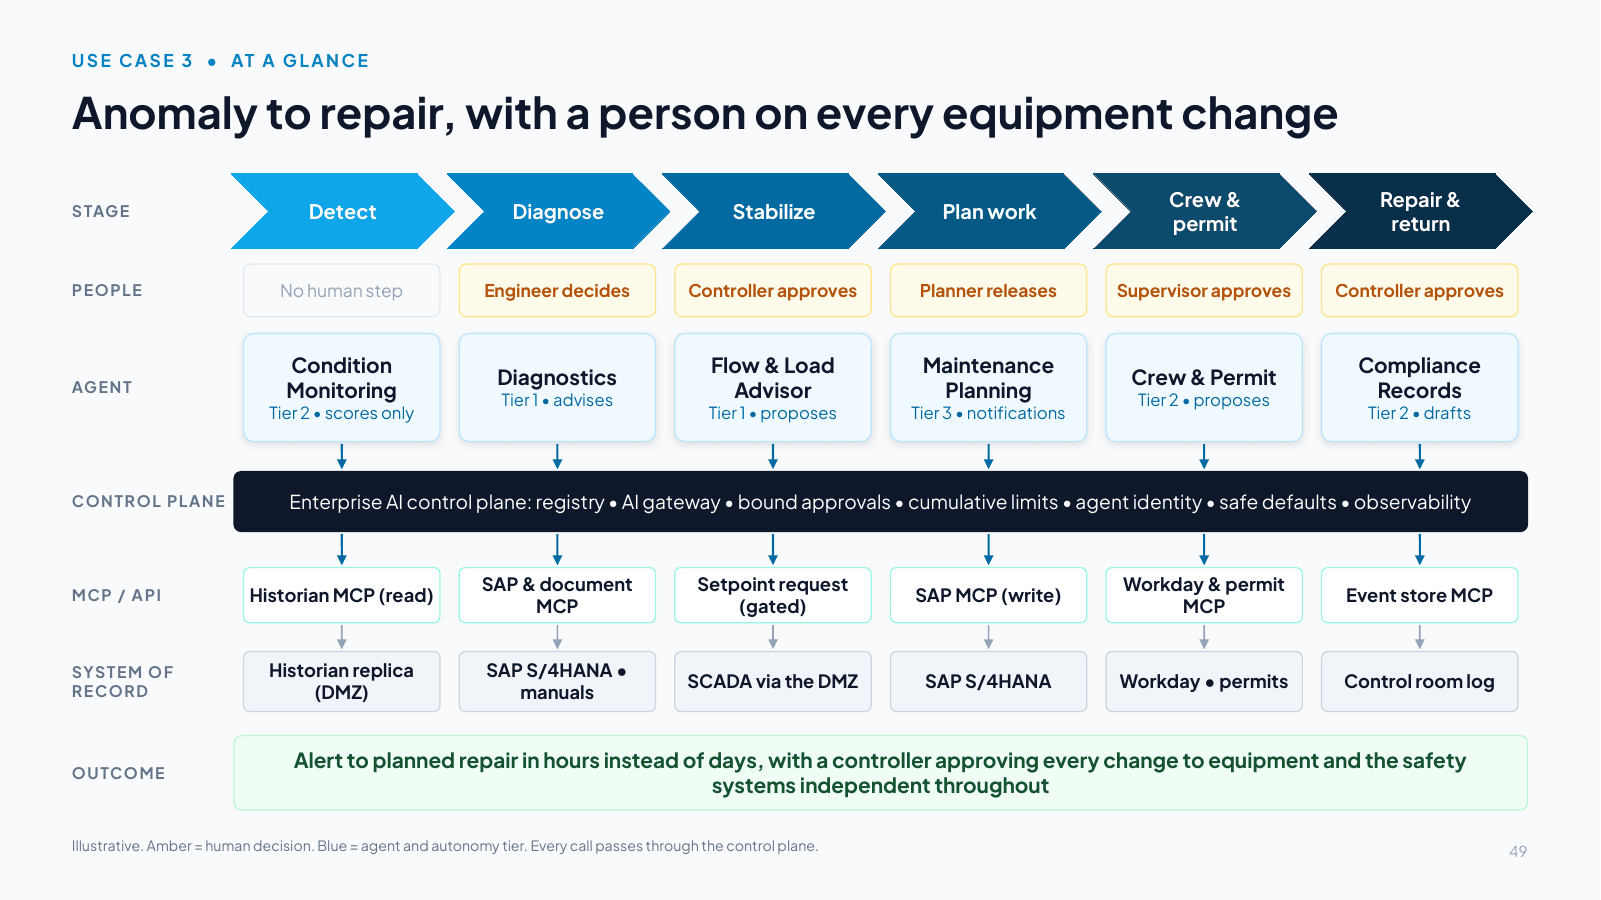
Anomaly to repair, with a person on every equipment change
Speaker notes
Walk the six stages left to right. For each, point to the human step (amber), the agent and its autonomy tier (blue), and the governed path underneath: agents reach systems only through the control plane and a governed MCP tool or API, and nothing reaches the control system except through the DMZ.
- Detect: the Condition Monitoring agent scores vibration, temperature and pressure trends from the historian replica (read-only, Tier 2).
- Diagnose: the Diagnostics agent suggests likely causes from maintenance history, similar events and manufacturer guidance. The reliability engineer decides (Tier 1).
- Stabilize: the Flow & Load Advisor proposes a load shift checked by the hydraulic model. The controller approves at the console, and the approval is bound to that exact change and valid for ten minutes (Tier 1).
- Plan work: the Maintenance Planning agent creates the notification, drafts the work order and reserves parts in SAP S/4HANA. The planner releases it.
- Crew & permit: the Crew & Permit agent confirms qualifications for the covered tasks [107] and drafts the isolation permit. The field supervisor approves on mobile.
- Repair & return: the controller approves the return to full load. The Compliance Records agent assembles the event record.
The outcome to land: alert to planned repair in hours instead of days (illustrative), with a controller approving every change to equipment and the safety systems independent throughout.
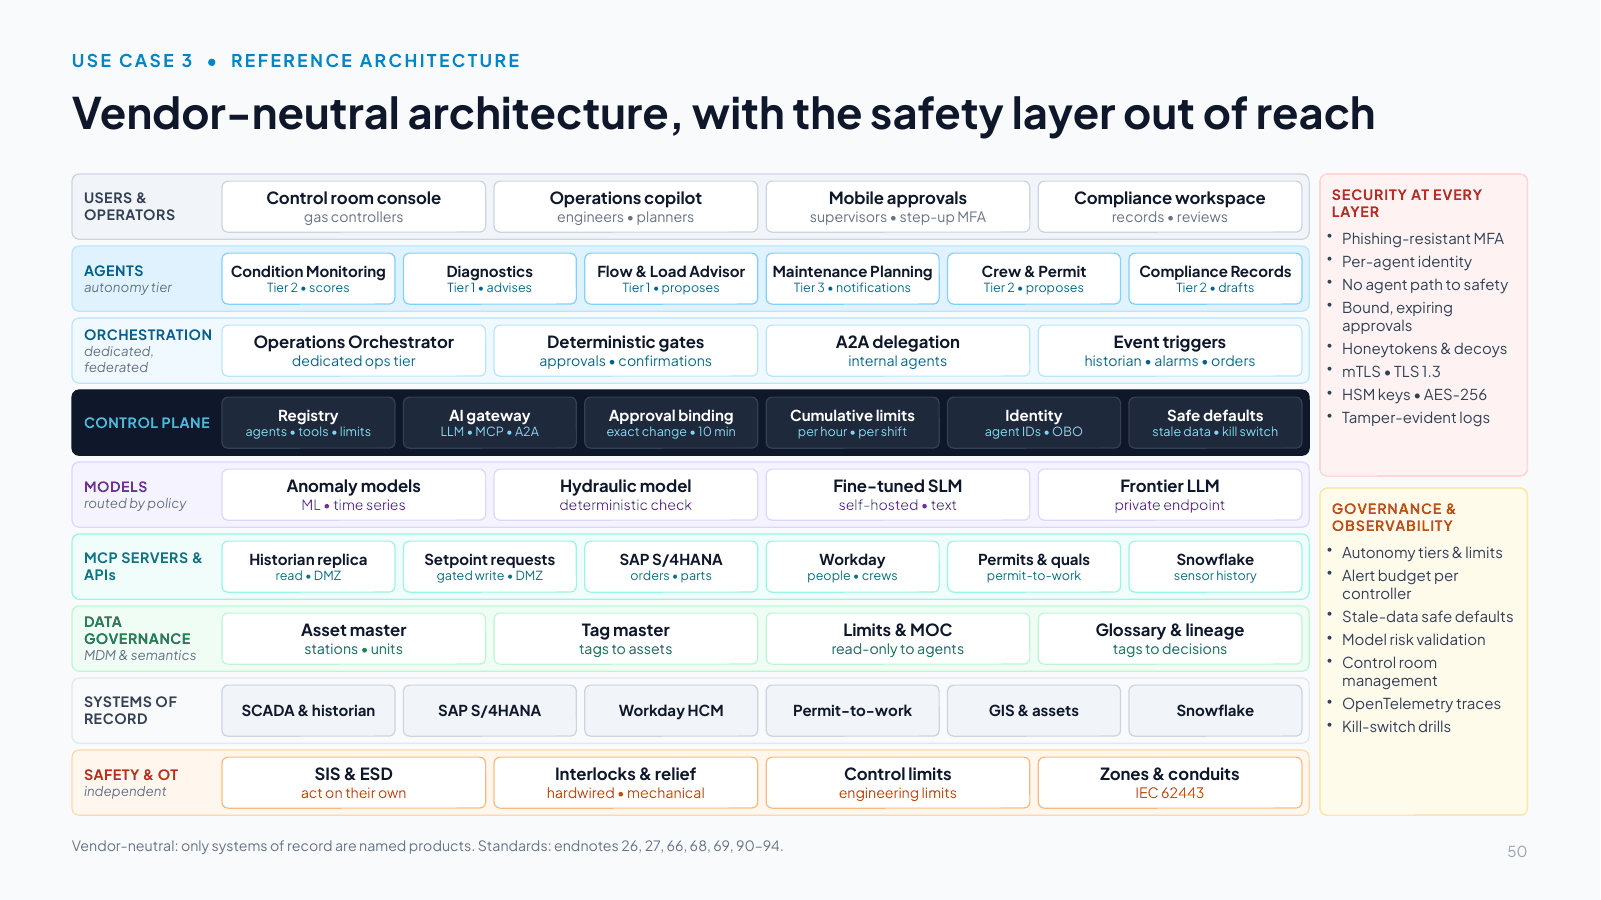
Vendor-neutral architecture, with the safety layer out of reach
Speaker notes
This is the vendor-neutral solution architecture, aligned to the north-star reference architecture, with one addition: a safety and OT layer beneath the systems of record that the agents cannot reach. Only the systems of record are named products.
Orchestration model selected: a dedicated orchestration tier for operations, federated under the enterprise control plane. Operations data and agents stay in the operator's own environment, close to the historian, while identity, policy, registry, audit and cost remain centrally governed. Orchestration is event-driven, with a supervisor pattern over A2A [27] and deterministic workflows for anything that touches equipment: a setpoint request always needs a controller's approval, and larger changes need a supervisor's confirmation.
Models and routing: anomaly models are conventional machine learning on time series. The operator's hydraulic model checks every proposed load shift deterministically and has the final word. A self-hosted small language model reads and drafts text, and a frontier model on a private endpoint summarizes diagnostics. Advice that rests on data that has since gone stale is discarded.
Control plane and policy: each approval is bound to the exact change and valid for ten minutes by the gateway's clock, with a supervisor as separate attester above a threshold. Cumulative caps limit flow re-allocation per hour and per shift across agents and sessions. Stale data (a feed more than 60 seconds old) drops the advisor to advice-only and voids pending requests, and alert budgets keep agent notifications within alarm-management limits. The binding and cumulative limits are custom Omni Gateway policies [78].
Security at every level: the design applies zero trust [90], with zones and conduits following ISA/IEC 62443 and NIST's OT security guide [68][69]. The only write path into operations is a setpoint-request service in the DMZ. Safety instrumented systems, emergency shutdown and interlocks stay independent of the agent path [66], and honeytokens and decoy tools in the DMZ flag any agent outside the governed path.
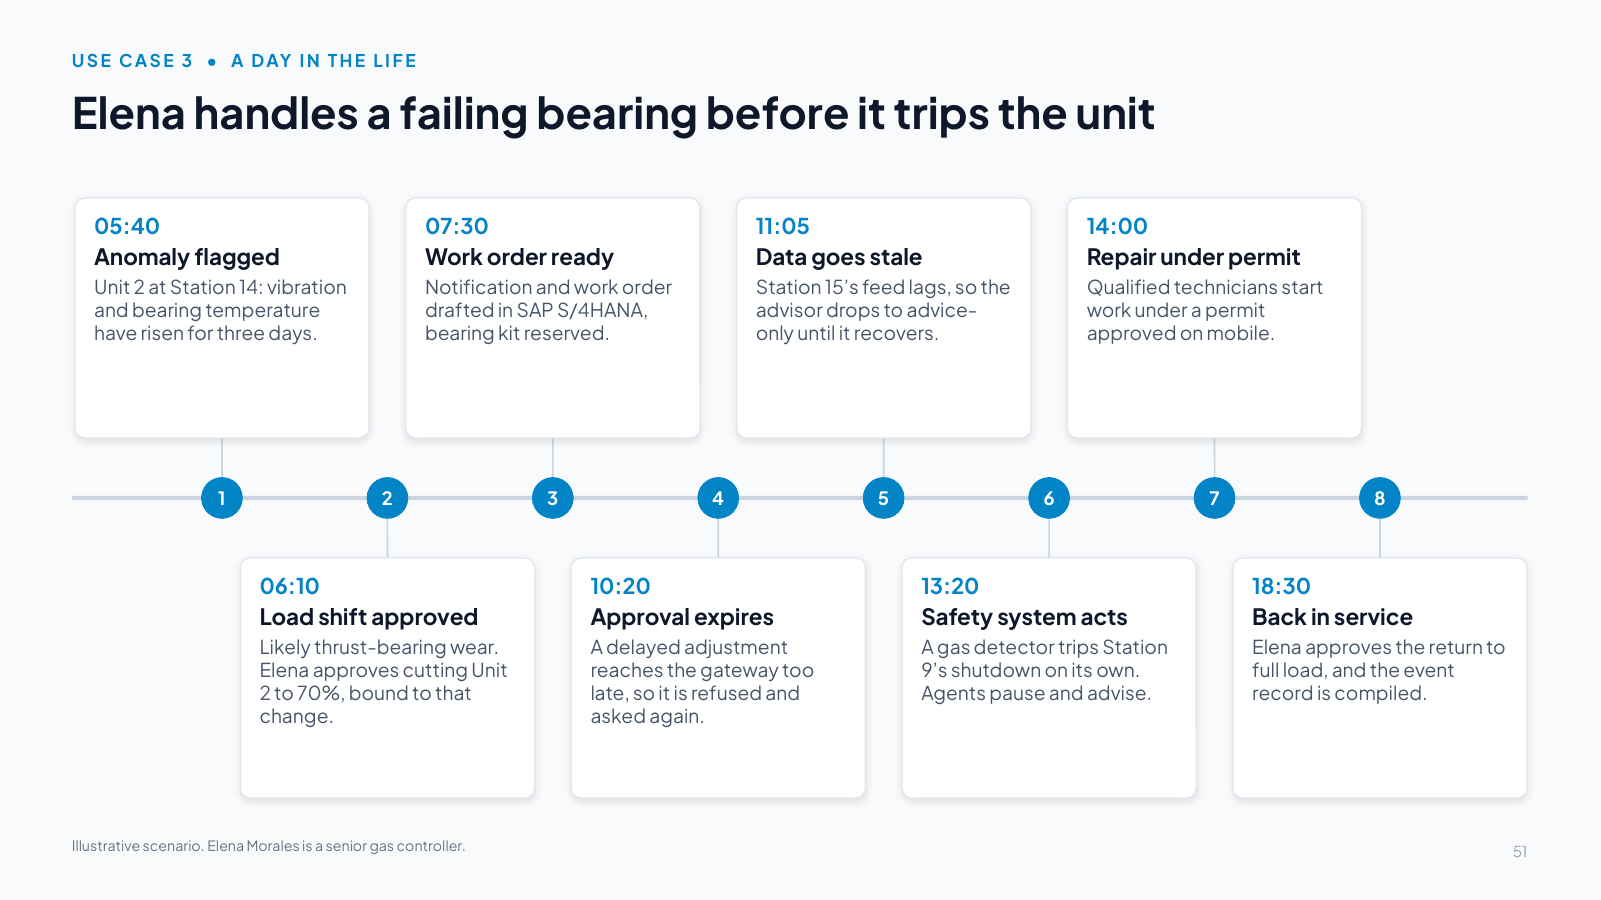
Elena handles a failing bearing before it trips the unit
Speaker notes
Tell Elena's day as a story.
At 05:40 the condition-monitoring agent flags Unit 2 at Station 14: vibration and bearing temperature have been rising for three days. By 06:00 the diagnostics agent has matched the pattern to two earlier thrust-bearing failures on the same model of unit and recommends an inspection within 24 hours at reduced load. At 06:10 the flow advisor proposes cutting Unit 2 to 70% and picking up the flow at Stations 13 and 15. The hydraulic model shows deliveries and pressures stay within limits. Elena approves at her console, next to the SCADA displays, and the change executes within its ten-minute window.
At 07:30 the planning agent has drafted the work order in SAP S/4HANA with the bearing kit reserved, and the planner releases it at 08:15. At 10:20 a second adjustment waits too long in the queue while Elena takes a shipper's call. Its approval has expired by the time it reaches the gateway, so it is refused and the advisor asks again with fresh values. When Station 15's data feed falls more than a minute behind at 11:05, the advisor drops to advice-only and voids a pending request until the feed recovers nine minutes later. At 13:20 a gas detector trips Station 9's emergency shutdown. The safety system acts on its own, and the agents pause requests for that segment and offer a re-balancing plan as advice. Qualified technicians start the repair at 14:00 under a permit their supervisor approved on mobile, and at 18:30 Elena approves the return to full load.
Leave the audience with this: people stayed in charge of every change to equipment, the safety systems never depended on the agents, and the repair happened in a planned window instead of after a trip.
How the components work together in Elena’s day
Speaker notes
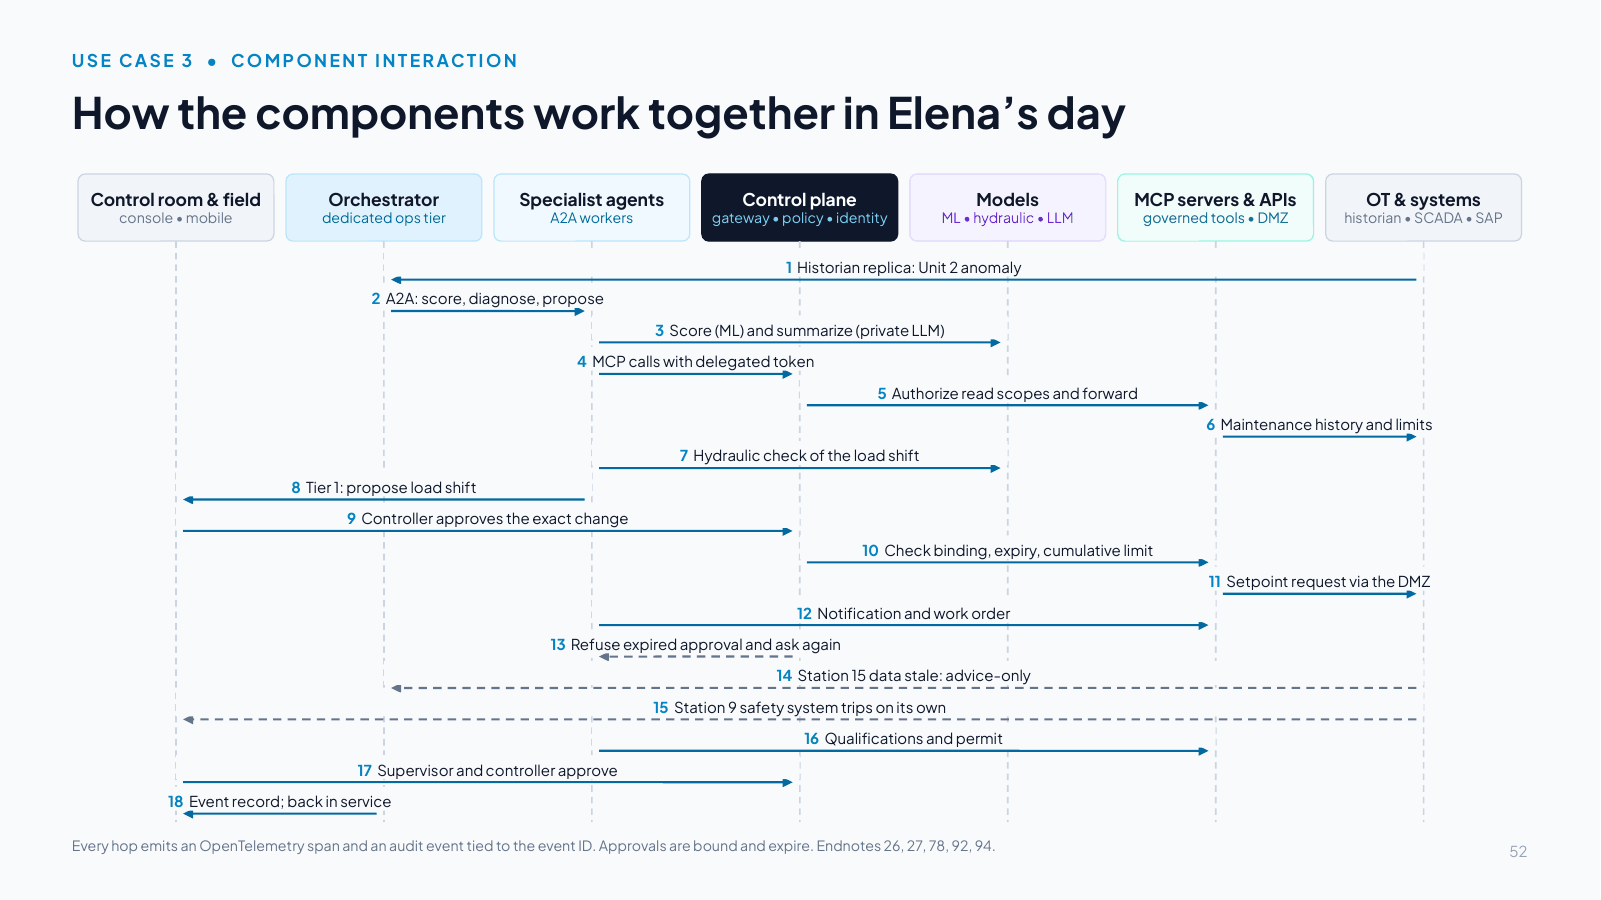
Read the numbered steps top to bottom. They follow Elena's day.
Steps 1–6 (05:40–06:00): the historian replica in the DMZ raises the anomaly, and the orchestrator delegates scoring and diagnosis over A2A [27]. The anomaly model scores Unit 2. The diagnostics agent reads maintenance history and engineering limits through MCP tools with a delegated token [92] and read-only scopes [26], and a private frontier model summarizes manufacturer guidance for the engineer.
Steps 7–11 (06:10): the Flow & Load Advisor runs the hydraulic check and proposes the load shift (Tier 1). Elena approves the exact change at the console. The control plane checks the binding, the ten-minute validity and the cumulative limit (custom Omni Gateway policies [78]). Only then does the setpoint-request service in the DMZ pass the change to the control system, which enforces its own engineering limits.
Step 12 (07:30): the planning agent creates the notification and work order through SAP S/4HANA tools.
Steps 13–15 (10:20–13:20): a delayed request is refused because its approval expired, and stale data from Station 15 drops the advisor to advice-only. When Station 9's safety system trips on its own, the agents only pause and advise.
Steps 16–18 (14:00–18:30): the crew agent confirms qualifications and drafts the permit, the supervisor and Elena approve, and the records agent compiles the event record. Every hop emits an OpenTelemetry span and an audit event [94].
Realized with MuleSoft Agent Fabric and Informatica
Speaker notes
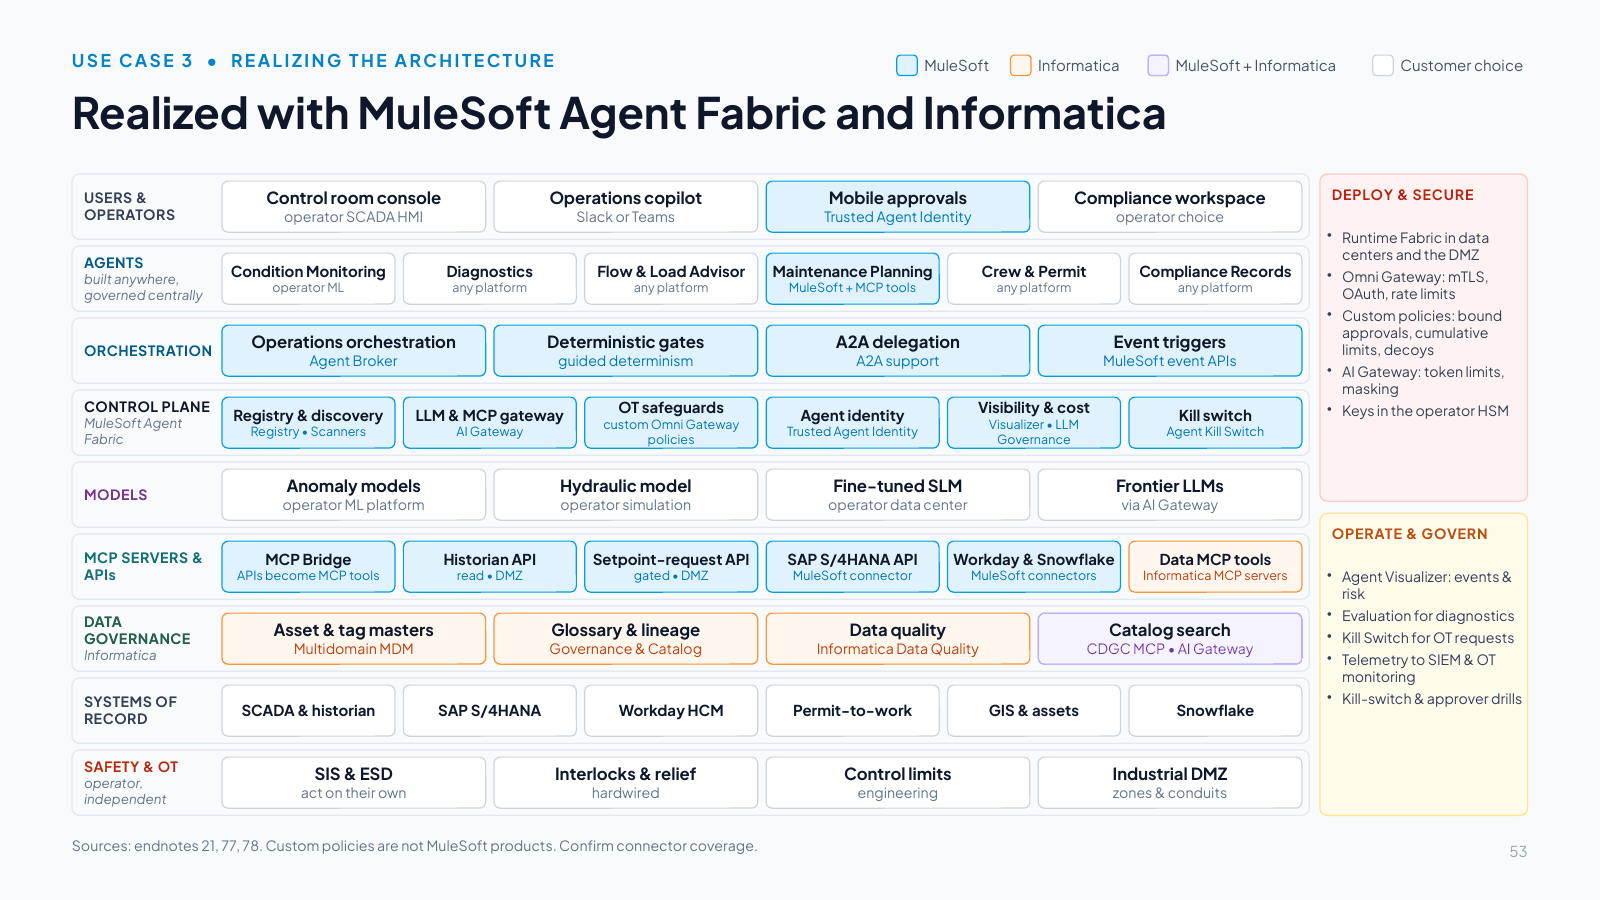
How MuleSoft Agent Fabric, custom Omni Gateway policies and Informatica realize the vendor-neutral design. Colors show which vendor fills each role. Grey boxes remain the operator's choice, including the control systems, historian, safety systems and models.
- Registry and discovery: Agent Registry and Agent Scanners register operations agents and agents embedded in vendor platforms, with owners, tiers and limits [21].
- Orchestration: Agent Broker with guided determinism enforces the fixed gates: no setpoint request without a controller's approval, no large change without a supervisor [21].
- Gateway: AI Gateway is the single policy point for LLM and MCP traffic. Omni Gateway applies mTLS, OAuth and rate limits to APIs and A2A [21][78].
- OT safeguards come from custom Omni Gateway policies built with the Policy Development Kit. Approval-to-Execution Binding checks that each setpoint request matches its approval and validity window, Cross-Session Aggregate-Risk Gate caps cumulative change across agents and sessions, and decoy and honeytoken policies flag agents outside the governed path [78]. They are custom code, supported by the operator or its partner, not MuleSoft products.
- Identity and control: Trusted Agent Identity supports on-behalf-of actions with mobile approval for permits and the return to service [21]. Agent Kill Switch stops all agent-originated OT requests in one action [21], and diagnostics and drafts are tested before release with the operator's evaluation tool.
- Tools: MCP Bridge and connectors for SAP S/4HANA, Workday and Snowflake. System APIs for the historian replica and permit-to-work (confirm connector coverage) [21].
- Data foundation (Informatica): Multidomain MDM holds asset, functional-location and tag golden records that agents reach through governed APIs, and data quality rules validate tag mappings and asset records, with exceptions routed to data stewards. Agents find data assets through the CDGC Metadata Search MCP server [77].
- Deployment: Runtime Fabric runs gateways, MCP servers and agents in the operator's data centers and industrial DMZ [21].
Expected business outcomes and KPIs
Speaker notes
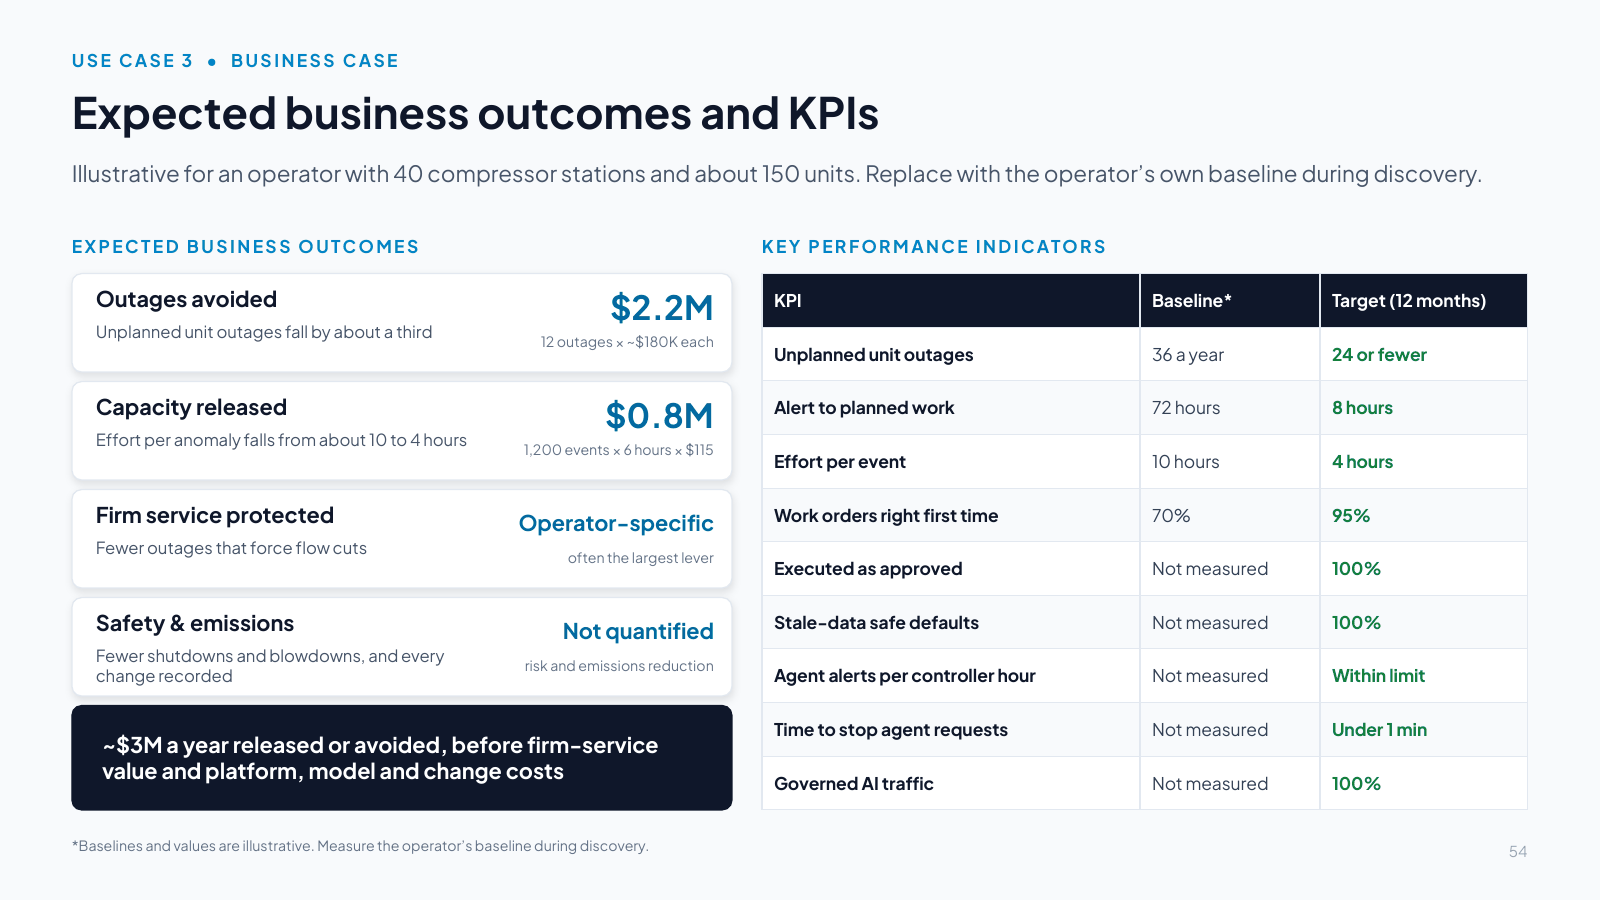
Business case, illustrative for an operator with 40 compressor stations and about 150 units, about 1,200 anomaly events and 36 unplanned unit outages a year:
- Outages avoided: earlier detection and planned repairs cut unplanned outages by about a third. 12 fewer outages × about $180,000 each (emergency repair premium, overtime and lost interruptible revenue) is about $2.2M a year.
- Capacity released: agents assemble diagnoses, work packages and permits, so effort per event falls from about 10 to 4 hours. 1,200 events × 6 hours × $115 is about $0.8M.
- Firm service protected: fewer outages that force flow cuts. The value is operator-specific and often the largest lever where outages constrain firm transportation.
- Safety and emissions: fewer emergency shutdowns and station blowdowns, and every change to equipment approved and recorded. Not quantified here; use the operator's own emissions factors.
Roughly $3M a year before firm-service value and before platform, model and change costs, which should be estimated alongside the baseline.
KPIs: the baselines are illustrative. The KPIs that speak directly to oversight and safety are setpoint requests executed exactly as approved and within their validity window (target 100%), stale-data events handled by the safe default (100%), agent alerts per controller hour within the alarm-management limit, and time to stop all agent-originated requests to OT in drills (under a minute).
How value builds across the four phases
Speaker notes
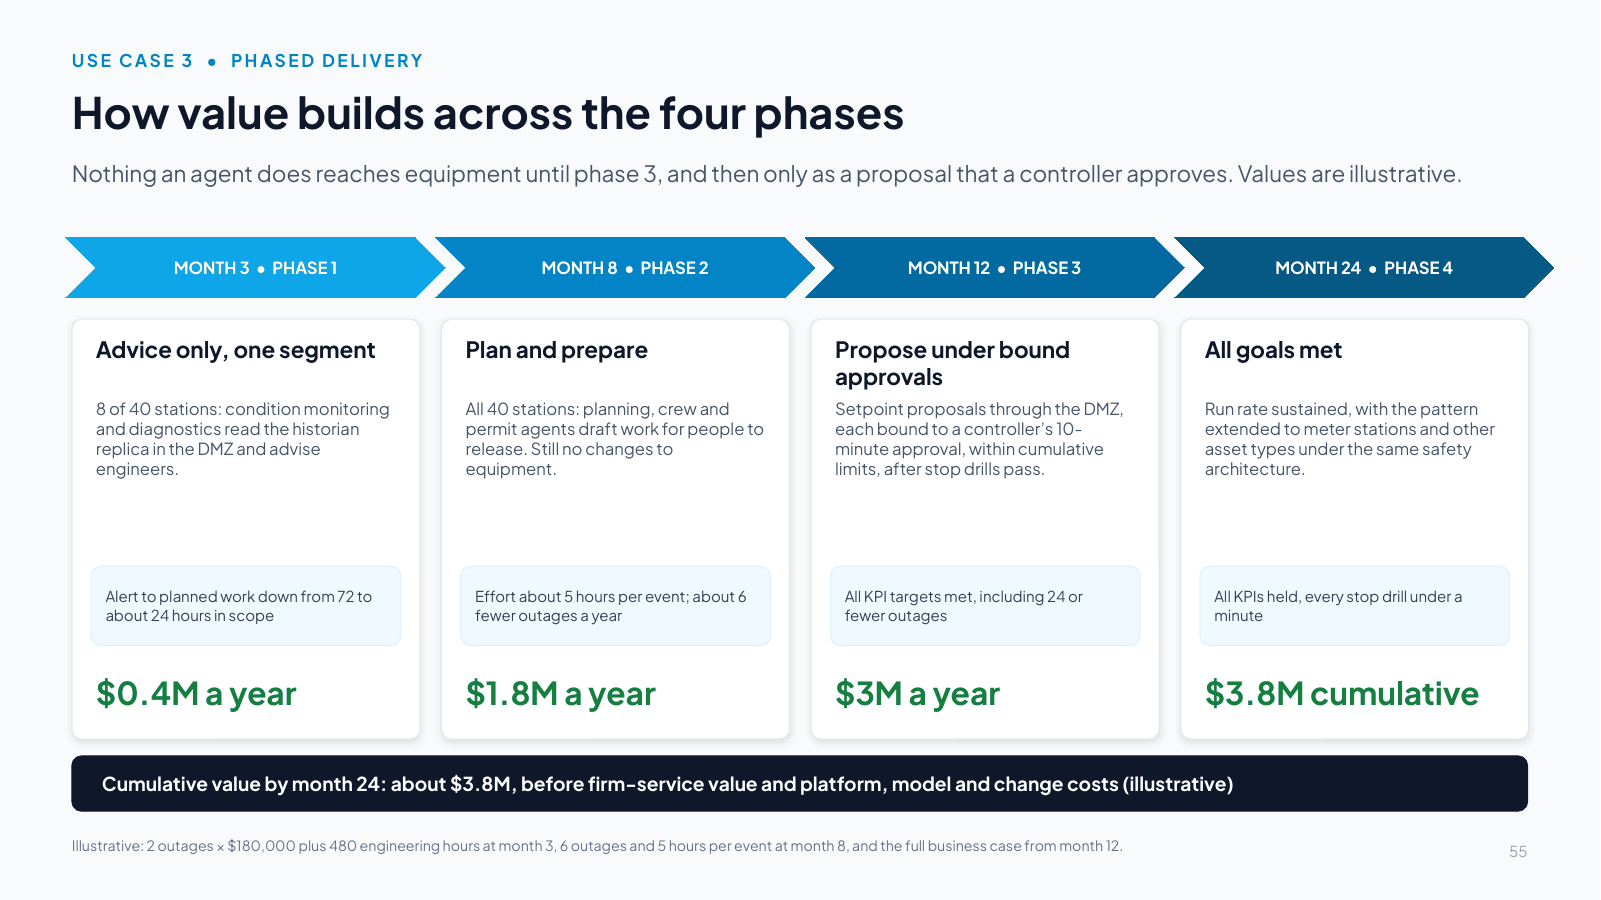
Phased delivery for the compressor use case, aligned with the four phases of the plan. Nothing an agent does reaches equipment until phase 3, and then only as a proposal that a controller approves.
- Month 3 (phase 1): one segment of the fleet, 8 of 40 stations. Condition monitoring and diagnostics agents read the historian replica in the DMZ and advise engineers at tiers 1–2. No agent tool can reach control or safety systems. About two outages a year are caught early (2 × $180,000) and engineering effort falls in scope (480 hours × $115): about $0.4M a year.
- Month 8 (phase 2): all 40 stations. Maintenance planning and crew and permit agents draft notifications, work orders and permits for planners and supervisors to release. About six fewer unplanned outages a year ($1.08M) and 5 hours of effort per event (1,200 × 5 × $115, about $0.69M): about $1.8M a year.
- Month 12 (phase 3): the flow and load advisor proposes setpoint changes through the DMZ. Each executes only with the controller's approval, bound to that exact change and valid for ten minutes, within cumulative limits and stale-data safe defaults, and only after drills show that people can stop agent requests in under a minute. All KPI targets are met: about $3M a year.
- Month 24 (phase 4): run rate sustained and the pattern extended to meter stations and other asset types. Cumulative value reaches about $3.8M by month 24.
All values are illustrative and before platform, model and change costs. Firm service protected, often the largest lever, is operator-specific and not included.
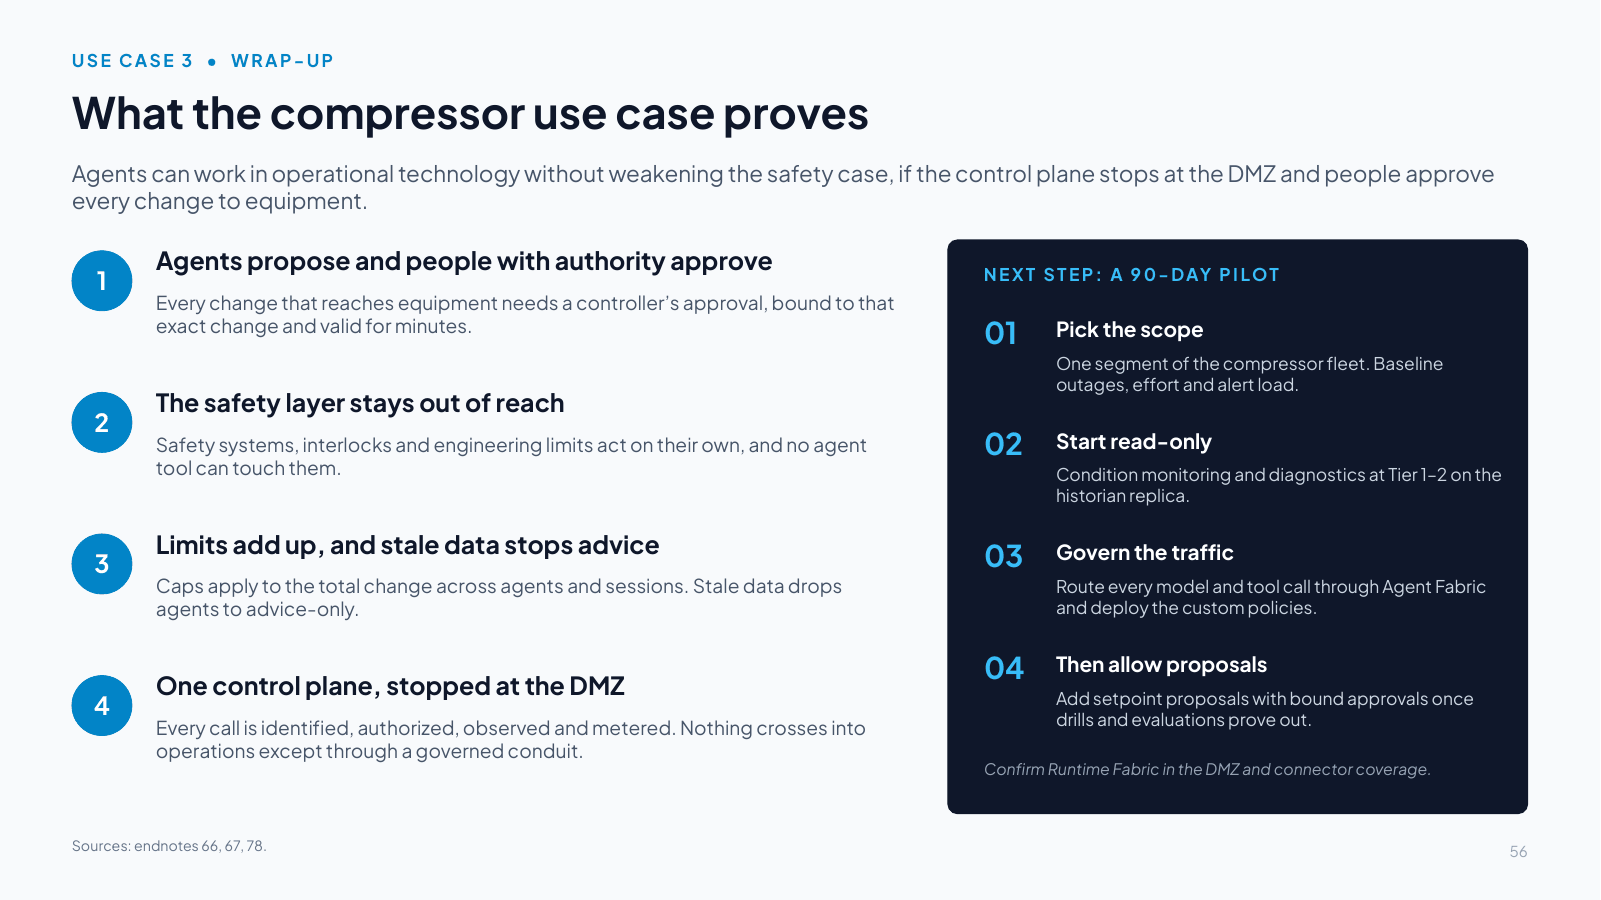
What the compressor use case proves
Speaker notes
Wrap up with what this use case proves:
- People with authority approve what agents propose. Every change that reaches equipment needs a controller's approval, bound to that exact change and valid for minutes, and larger changes need a supervisor as a separate attester.
- The safety layer stays out of reach. Safety instrumented systems, emergency shutdown, interlocks and engineering limits act on their own. No agent tool can read or write safety logic, bypass an interlock or acknowledge a safety alarm [66][67].
- Limits add up, and stale data stops advice. Cumulative caps apply across agents and sessions, and a stale feed drops agents to advice-only. The process falls back to its engineered safe state, not a blanket stop.
- One control plane, stopped at the DMZ. Every call is identified, authorized, observed and metered, and nothing crosses into operations except through a governed conduit.
Proposed next step: a 90-day pilot. Scope one segment of the compressor fleet and baseline outages, effort and alert load. Start read-only with condition monitoring and diagnostics at Tier 1–2 on the historian replica. Route every model and tool call through Agent Fabric and deploy the custom Omni Gateway policies [78]. Add setpoint proposals with bound approvals only once kill-switch and approver drills and evaluations prove out.
Before committing dates, confirm Runtime Fabric deployment in the DMZ and connector coverage for the historian and permit systems.